path
The path module allows users to explore different paths, filter relationships,
and nodes based on specific criteria, and achieve more complex path-related
tasks that go beyond the capabilities of native Cypher - whether you’re seeking
all possible paths between two nodes, subgraphs that meet certain conditions, or
various other path-oriented operations.
| Trait | Value |
|---|---|
| Module type | algorithm |
| Implementation | C++ |
| Graph direction | directed/undirected |
| Edge weights | weighted/unweighted |
| Parallelism | sequential |
You can execute this algorithm on graph projections, subgraphs or portions of the graph.
Functions
elements()
The function converts the given path into a list with the node-relationship-node order.
Input:
path: Path➡ The given path.
Output:
List[Node|Relationship]➡ The given path in the form of node-relationship-node.
Usage:
Use the following query to convert a path into a list of graph objects:
CREATE (:Node1)-[:CONNECTED]->(:Node2)-[:CONNECTED]->(:Node3)-[:CONNECTED]->(:Node4)-[:CONNECTED]->(:Node5);
MATCH path = (:Node1)-[:CONNECTED*4]->(:Node5)
RETURN path.elements(path) AS result;
The result is returned in shortened form with () signifying nodes and [] signifying relationships.
+------------------------------------------------------------------------------------------------------------------+
| result                                                                                                           |
+------------------------------------------------------------------------------------------------------------------+
| [(:Node1), [:CONNECTED], (:Node2), [:CONNECTED], (:Node3), [:CONNECTED], (:Node4), [:CONNECTED], (:Node5)]       |
+------------------------------------------------------------------------------------------------------------------+
combine()
The function combines two given paths into one. The end of the first path and the beginning of the second path must match. Throws an exception if the given paths can’t be combined.
Input:
first: Path➡ The first path. Ifnull, the function returns the second path.second: Path➡ The second path. Ifnull, the function returns the first path.
If both paths are null, the function returns null.
Output:
Path➡ The combined path.
Usage:
Use the following query to combine two paths into one:
CREATE (:Node1)-[:CONNECTED]->(:Node2)-[:CONNECTED]->(:Node3)-[:CONNECTED]->(:Node4)-[:CONNECTED]->(:Node5)-[:CONNECTED]->(:Node6);

MATCH (node1:Node1), (node4:Node4), (node6:Node6)
MATCH path1 = (node1)-[:CONNECTED*3]->(node4)
MATCH path2 = (node4)-[:CONNECTED*2]->(node6)
RETURN path.combine(path1, path2) AS result;
The result is returned in shortened form with () signifying nodes and [] signifying relationships.
+-----------------------------------------------------------------------------------------------------------------------------+
| result                                                                                                                      |
+-----------------------------------------------------------------------------------------------------------------------------+
| (:Node1)-[:CONNECTED]->(:Node2)-[:CONNECTED]->(:Node3)-[:CONNECTED]->(:Node4)-[:CONNECTED]->(:Node5)-[:CONNECTED]->(:Node6) |
+-----------------------------------------------------------------------------------------------------------------------------+
slice()
The function returns a subpath of the given path.
Input:
path: Path➡ The given path.offset: int = 0➡ The first node index from the given path to be included in the subpath. A negative offset is read as0, and an offset past the end of the given path starts the subpath at its final node.length: int = -1➡ Length of the subpath. If set to -1 the subpath will end on the final node of the given path. A length reaching past the end of the given path ends the subpath on its final node, and any other negative length returns a subpath with no relationships.
Output:
Path➡ The subpath of the given path.
An offset or length outside the given path is adjusted to the nearest subpath
rather than raising an error, so bounds computed from an expression such as
length(path) can be passed without guarding them first. The shortest subpath
the function returns is a single node.
Usage:
Use the following query to return a subpath of the given path:
CREATE (:Node1)-[:CONNECTED]->(:Node2)-[:CONNECTED]->(:Node3)-[:CONNECTED]->(:Node4)-[:CONNECTED]->(:Node5);

MATCH path = (:Node1)-[:CONNECTED*4]->(:Node5)
RETURN path.slice(path, 1, -1) AS result;
The result is returned in shortened form with () signifying nodes and [] signifying relationships.
+------------------------------------------------------------------------------------------------------+
| result                                                                                               |
+------------------------------------------------------------------------------------------------------+
| (:Node2)-[:CONNECTED]->(:Node3)-[:CONNECTED]->(:Node4)-[:CONNECTED]->(:Node5)                        |
+------------------------------------------------------------------------------------------------------+
Use the following query to see how bounds outside the given path are adjusted:
MATCH path = (:Node1)-[:CONNECTED*4]->(:Node5)
RETURN path.slice(path, -5, 2) AS negative_offset,
       path.slice(path, 10, -1) AS offset_past_end,
       path.slice(path, 1, -3) AS negative_length;
The negative offset starts the subpath at the first node, the offset past the end returns the final node on its own, and the negative length returns a subpath with no relationships:
+--------------------------------------------------------+--------------------------------------------------------+--------------------------------------------------------+
| negative_offset                                        | offset_past_end                                        | negative_length                                        |
+--------------------------------------------------------+--------------------------------------------------------+--------------------------------------------------------+
| (:Node1)-[:CONNECTED]->(:Node2)-[:CONNECTED]->(:Node3) | (:Node5)                                               | (:Node2)                                               |
+--------------------------------------------------------+--------------------------------------------------------+--------------------------------------------------------+
Procedures
create()
The procedure creates a path from the given starting node and a list of relationships. Iteratively appends all relationships in the list to the new path until a relationship is null (as a result of optional match) or a relationship from the last node of the path to one of the nodes in the current relationship (the one that isn’t the last one in the path) doesn’t exist.
Input:
-
subgraph: Graph(OPTIONAL) ➡ A specific subgraph, which is an object of type Graph returned by theproject()function, on which the algorithm is run. If subgraph is not specified, the algorithm is computed on the entire graph by default. -
start_node: Node- The starting node of the path. A null value yields no rows. -
relationships: Map (default={key: []})- A map with the keyrelthat contains a list of the given relationships. A map without arelkey means no relationships to append, sopath.create(n)returns a path made of the start node alone.
Output:
path: Path- The created path.
Usage:
Use the following query to create a path from the given starting node and a list of relationships:
MERGE (croatia:Country {name: 'Croatia'})
MERGE (madrid:City {name: 'Madrid'})
MERGE (kutina:City {name: 'Kutina'})
MERGE (real:Club {name: 'Real Madrid'})
MERGE (moslavina:Club {name: 'NK Moslavina'})
MERGE (kutina)-[:In_country]->(croatia)
MERGE (moslavina)-[:In_city]->(kutina)
MERGE (real)-[:In_city]->(madrid);

MATCH (club:Club) OPTIONAL MATCH (club)-[inCity:In_city]->(city:City)
OPTIONAL MATCH (city)-[inCountry:In_country]->(:Country)
CALL path.create(club, {rel:[inCity, inCountry]})
YIELD path
RETURN path;
Result:
+------------------------------------------------------------------------------------------------------------------+
| path                                                                                                             |
+------------------------------------------------------------------------------------------------------------------+
| ((:Club {name: 'Real Madrid'})-[:In_city]->(:City {name: 'Madrid'}))                                                |
+------------------------------------------------------------------------------------------------------------------+
| ((:Club {name: 'NK Moslavina'})-[:In_city]->(:City {name: 'Kutina'})-[:In_country]->(:Country {name: 'Croatia'}))    |
+------------------------------------------------------------------------------------------------------------------+
expand()
The procedure expands from the start node(s) following the given relationships and label filters, from min to max number of allowed hops. Return all paths inside the allowed number of hops, which satisfy relationship and label filters.
Input:
-
subgraph: Graph(OPTIONAL) ➡ A specific subgraph, which is an object of type Graph returned by theproject()function, on which the algorithm is run. If subgraph is not specified, the algorithm is computed on the entire graph by default. -
start: any➡ A node, node ID, or a list of nodes and/or node IDs from which the function will expand. -
relationships: List[string]➡ A list of relationships which the expanding will follow. Relationships can be filtered using the notation described below. -
labels: List[string]➡ A list of labels which will define filtering. Labels can be filtered using the notation described below. -
min_hops: int➡ The minimum number of hops for a path to be returned. -
max_hops: int➡ The maximum number of hops for a path to be returned.-1means no limit; any other negative value is a real bound and matches nothing.
A null start yields no rows instead of raising a type error. A null inside a list of start nodes
is still an error, as is an ID no node carries, so a list gathered from an OPTIONAL MATCH does need
guarding.
expand() always walks depth-first, recursing once per hop, so it is bounded at a depth of 5000 hops
and returns an error beyond it — an unbounded max_hops over a long chain would otherwise exhaust the
stack. An unbounded traversal can still build an arbitrarily large result set, so set
--memory-limit to keep one a recoverable query error.
Relationship filters:
| Option | Explanation |
|---|---|
TYPE | Path will expand with either outgoing or incoming relationships of this type. |
<TYPE | Path will expand with incoming relationships of this type. |
TYPE> | Path will expand with outgoing relationships of this type. |
> | Path will expand with all outgoing relationships. |
< | Path will expand will all incoming relationships. |
If the relationship filter is empty, all relationship types are allowed.
A < or > marker counts wherever it appears in the entry, and < takes precedence when both are
present. <TYPE, TYPE< and <TYPE> therefore all name the same incoming filter, and <> matches
every type, incoming. A : is ignored, so :TYPE and TYPE are the same filter — which also means a
relationship type whose name contains <, > or : cannot be filtered on by name.
Two entries for the same type merge rather than replace each other, so ['TYPE>', '<TYPE'] allows the
type in both directions regardless of the order the entries were listed in.
An entry that names neither a relationship type nor a direction is an error — an empty entry such as
[''], or one made only of separators such as ':'.
path.expand takes a list of strings; the single |-separated string form is available only on the
config-map procedures, and is described under expand_config().
Examples:
Relationship list : [<LOVES, >]: path will expand on all outgoing relationships, and incoming relationshipLOVES.Relationship list : [<LOVES, LOVES]: path will expand on incoming relationshipLOVES, and all directions of relationshipLOVES, making the first element in the relationship list functionally obsolete.Relationship list : []: path will expand on all relationships.
Label filters:
| Option | Explanation |
|---|---|
+LABEL | Label is added to the whitelist. All nodes in the path must have a label in the whitelist. If the whitelist is empty, it is as if all nodes are whitelisted. |
>LABEL | Label is added to the end list. When end list has labels, only paths ending with these labels will be returned, but they can be expanded further, to return paths ending in nodes with end labels beyond it. An end-listed node is expanded through whether or not it is whitelisted; every other node on the path must satisfy the whitelist. |
-LABEL | Label is added to the blacklist. No node in the path will contain labels in the blacklist. The blacklist takes precedence over all other filters. |
/LABEL | Label is added to the termination list. When termination list contains labels, only paths ending with these labels will be returned, and any further expansion is stopped. Labels in the termination list do not have to respect the whitelist. |
* | Matches every label, under any of the four prefixes. * and +* whitelist every node, -* blacklists every one, >* makes every node an end node and /* a termination node. This is how one step of a sequence says “any label in this position”. |
An empty entry, or a bare +, -, > or / with no label behind it, is an error rather than a
filter that matches nothing.
* is a label wildcard only. A relationship filter says “any type” with a bare direction marker
instead — '>', '<', or '<|>' for either direction, that last one as a string rather than a list
entry — and a relationship entry that is just *,
once any <, > or : is discounted, is an error naming those spellings. A * alongside a type
name is not: 'CATCHES*' is read as a type of that literal name and matches nothing.
With filterStartNode at its default the start node is exempt from the label filter entirely — its
own labels are never consulted — so a label on the whitelist or blacklist that would exclude it does
not stop it being returned. An end or termination filter is the exception: a > or / prefix decides which
nodes come back at all, and an exempt start node is not one of them, whatever its labels are. Setting
filterStartNode: true on a config-map procedure filters it like any other node — the positional
expand() has no such argument — which is also what lets a start node
carrying an end or termination label be returned.
A node in the termination list ends the walk only once it can actually be returned. Below the lower
hop bound the node is left out of the results and the walk continues through it, so combining a
/LABEL with a minHops or minLevel above 1 no longer discards every path beyond the first
matching node.
Any other label syntax is added to the whitelist. For example, LABEL will be
added to the whitelist as LABEL, and !LABEL will be added to the whitelist
as !LABEL.
To know where the label will be added, look at the first element of the label.
For example, >LABEL> will be added to the end list as LABEL>.
Examples:
Consider the graph provided in the usage section below. In this subsection,
number of hops will be limited from 0 to 2, and the starting node will be Dog.
Label list: ["/Mouse"]- The filtering will return all the paths ending withMouse. Because no labels were added to the whitelist, all labels are considered whitelisted. The filtering will return 3 paths:Dog->Cat->Mouse,Dog<-Human->Mouse,Dog->Mouse.Label list: ["/Mouse", "Cat"]- Now, labelCatis added to the whitelist, becoming the only whitelisted label. The meaning of the filter can now be represented as:"return all paths ending with Mouse, which expand through Cat and Cat only". This filtering will return two paths, one whereDogconnects to theMousedirectly(Dog->Mouse), and one whereCatis included (Dog->Cat->Mouse).Label list: ["/Mouse", "-Cat", "-Human"]- Now, bothCatandHumanare blacklisted, and there is only one eligible path that can reachMouse:Dog->Mouse.
For the final example, the starting node is Cat, and the maximum number of
hops is increased to 4.
Label list: [">Dog", "+Human", "+Wolf"]- Now, only paths ending withDogwill be returned, but they can be further expanded through the nodes with whitelisted labels. This filtering returns 3 paths:Cat<-Dog,Cat<-Dog<-Human->Wolf->Dog,Cat<-Dog<-Wolf<-Human->Dog.
Output:
result: Path➡ all paths expanded from the start node.
Usage:
The database contains the following data:
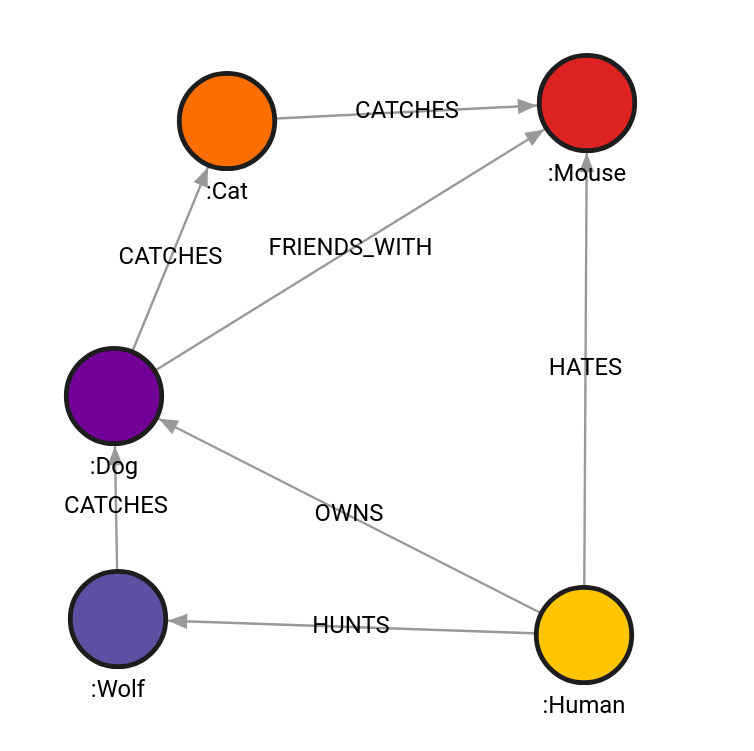
Created with the following Cypher queries:
CREATE (w:Wolf)-[ca:CATCHES]->(d:Dog), (c:Cat), (m:Mouse), (h:Human);
MATCH (w:Wolf), (d:Dog), (c:Cat), (m:Mouse), (h:Human)
WITH w, d, c, m, h
CREATE (d)-[:CATCHES]->(c)
CREATE (c)-[:CATCHES]->(m)
CREATE (d)-[:FRIENDS_WITH]->(m)
CREATE (h)-[:OWNS]->(d)
CREATE (h)-[:HUNTS]->(w)
CREATE (h)-[:HATES]->(m);
Example 1
The query will expand from Dog labeled nodes on outgoing relationship CATCHES and
incoming relationship HATES, with Mouse and Human being labels in end
list. Whitelist is empty, hence, all labels are whitelisted.
MATCH (w:Wolf), (d:Dog), (c:Cat), (m:Mouse), (h:Human)
CALL path.expand(d,["CATCHES>","<HATES"],[">Mouse", ">Human"],0,4) YIELD result RETURN result;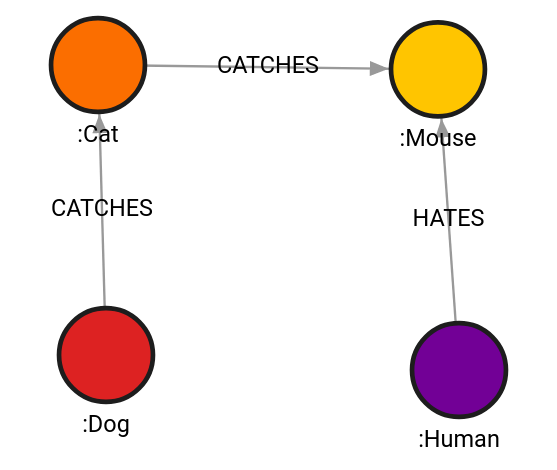
| result |
|---|
{"nodes":[{"id":1,"labels":["Dog"],"properties":{},"type":"node"},{"id":2,"labels":["Cat"],"properties":{},"type":"node"},{"id":3,"labels":["Mouse"],"properties":{},"type":"node"}],"relationships":[{"id":1,"start":1,"end":2,"label":"CATCHES","properties":{},"type":"relationship"},{"id":2,"start":2,"end":3,"label":"CATCHES","properties":{},"type":"relationship"}],"type":"path"} |
{"nodes":[{"id":1,"labels":["Dog"],"properties":{},"type":"node"},{"id":2,"labels":["Cat"],"properties":{},"type":"node"},{"id":3,"labels":["Mouse"],"properties":{},"type":"node"},{"id":4,"labels":["Human"],"properties":{},"type":"node"}],"relationships":[{"id":1,"start":1,"end":2,"label":"CATCHES","properties":{},"type":"relationship"},{"id":2,"start":2,"end":3,"label":"CATCHES","properties":{},"type":"relationship"},{"id":6,"start":4,"end":3,"label":"HATES","properties":{},"type":"relationship"}],"type":"path"} |
Example 2
The query will expand from the Dog labeled node only on incoming
relationships. Also, label Human is blacklisted.
MATCH (w:Wolf), (d:Dog), (c:Cat), (m:Mouse), (h:Human)
CALL path.expand(d,["<"],["-Human"],0,4) YIELD result RETURN result;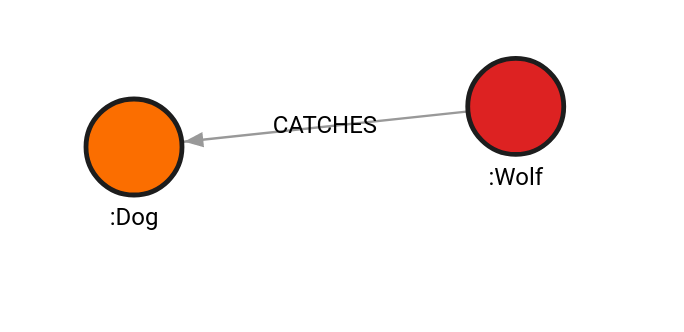
| result |
|---|
{"nodes":[{"id":1,"labels":["Dog"],"properties":{},"type":"node"}],"relationships":[],"type":"path"} |
{"nodes":[{"id":1,"labels":["Dog"],"properties":{},"type":"node"},{"id":0,"labels":["Wolf"],"properties":{},"type":"node"}],"relationships":[{"id":0,"start":0,"end":1,"label":"CATCHES","properties":{},"type":"relationship"}],"type":"path"} |
Example 3
The query will expand from Dog and Mouse labeled nodes. Cat is the
termination label, and the maximum number of hops is 1. Also, Mouse is passed
as ID, to demonstrate that capability of the expand function.
MATCH (w:Wolf), (d:Dog), (c:Cat), (m:Mouse), (h:Human)
CALL path.expand([d, id(m)],[],["/Cat"],0,1) YIELD result RETURN result;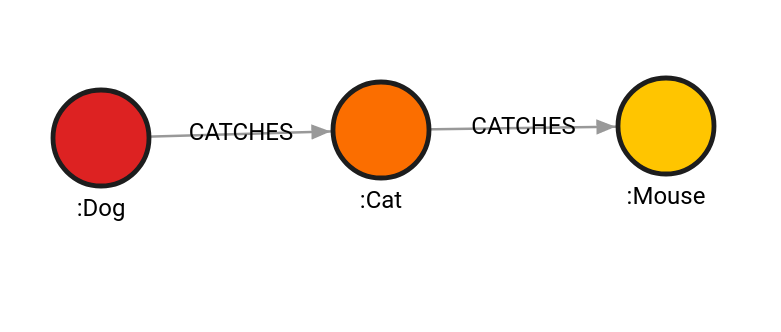
| result |
|---|
{"nodes":[{"id":1,"labels":["Dog"],"properties":{},"type":"node"},{"id":2,"labels":["Cat"],"properties":{},"type":"node"}],"relationships":[{"id":1,"start":1,"end":2,"label":"CATCHES","properties":{},"type":"relationship"}],"type":"path"} |
{"nodes":[{"id":3,"labels":["Mouse"],"properties":{},"type":"node"},{"id":2,"labels":["Cat"],"properties":{},"type":"node"}],"relationships":[{"id":2,"start":2,"end":3,"label":"CATCHES","properties":{},"type":"relationship"}],"type":"path"} |
expand_config()
The config-map form of expand(). It expands from the start node(s) and returns every path
within the hop bounds that satisfies the filters, taking its arguments as a map rather than a fixed
argument list — which is what makes the node-identity filters, limit and uniqueness available.
Input:
-
subgraph: Graph(OPTIONAL) ➡ A specific subgraph, which is an object of type Graph returned by theproject()function, on which the algorithm is run. If subgraph is not specified, the algorithm is computed on the entire graph by default. -
start: Any➡ A node, node ID, or a list of nodes and/or node IDs from which the procedure will expand. A null value yields no rows. -
config: Map➡ The configuration parameters. Required — pass{}to take every default:
| Name | Type | Default | Description |
|---|---|---|---|
| minHops | Int | 0 | The minimum number of hops for a path to be returned. minLevel is an alias. |
| maxHops | Int | -1 | The maximum number of hops for a path to be returned. -1 means no limit; any other negative value matches nothing. maxLevel is an alias. |
| relationshipFilter | List or String | [ ] | Relationships the expansion will follow, using the notation described under expand(). |
| labelFilter | List or String | [ ] | Labels which will define filtering, using the notation described under expand(). |
| filterStartNode | Bool | False | Whether the label and node-identity filters apply to the start node. |
| bfs | Bool | True | Emit every path of one length before any longer one, so a limit returns the shortest paths. false expands depth-first, holding only the current path rather than every partial one. Under RELATIONSHIP_PATH and NODE_PATH both modes return the same paths and differ only in order; under NODE_GLOBAL they return different paths, because a node is spent at the depth the walk first reaches it. |
| limit | Int | -1 | The maximum number of paths to return. The traversal stops once the cap is reached rather than building the rest of the result and discarding it, which a trailing Cypher LIMIT cannot do. With several start nodes they are walked in the order they were listed, so that order decides which paths a limit returns. -1 means no limit; a value below -1 is an error. |
| uniqueness | String | RELATIONSHIP_PATH | What may not repeat. RELATIONSHIP_PATH and NODE_PATH forbid a repeat within a single path, and allow a node or relationship to appear in other paths. NODE_GLOBAL forbids a node repeating anywhere in the traversal, so at most one path per reachable node is returned. |
| sequence | String | "" | One alternating string of label and relationship steps — a label step, then a relationship step, then a label step, and so on. Supersedes labelFilter and relationshipFilter when given. See sequences. |
| beginSequenceAtStart | Bool | True | Whether a sequence begins at the start node or one hop out from it. See sequences. |
| endNodes | List | [ ] | Nodes, or node IDs, that are returned and expanded through — the node-identity counterpart of the >LABEL prefix. With either this or terminatorNodes set, only the nodes they name end a returned path. |
| terminatorNodes | List | [ ] | Nodes, or node IDs, that are returned and end the walk — the node-identity counterpart of the /LABEL prefix. |
| allowlistNodes | List | [ ] | Nodes, or node IDs, the traversal is restricted to. An empty list allows every node. Nodes named by endNodes or terminatorNodes are allowed implicitly, so an allowlist that does not mention them still reaches them. |
| denylistNodes | List | [ ] | Nodes, or node IDs, the traversal will not return or pass through. Takes precedence over allowlistNodes. |
whitelistNodes and blacklistNodes are accepted as deprecated spellings of allowlistNodes and
denylistNodes, and are read only when the preferred key is absent or empty.
A key this procedure does not recognize is an error, naming the key, rather than being ignored. So is
supplying minHops together with minLevel, or maxHops together with maxLevel. The deprecated
node-list spellings are not rejected that way — giving both is allowed, and the preferred key wins. optional
is not an accepted key: a call relying on it raises an error rather than yielding a null row for a
start node the expansion found nothing from.
filterStartNode decides whether the start node is filtered, by label and by node identity alike. The
one exception is a sequence that begins one hop out: with beginSequenceAtStart: false the start node
has no label step to be tested against, so the label filter does not apply to it however
filterStartNode is set. The node-identity filters still follow filterStartNode.
The labelFilter, the endNodes/terminatorNodes lists and the allowlistNodes/denylistNodes
lists are evaluated independently and combined: a node is returned only if every active one includes
it, and any one of them can stop the walk. So a labelFilter and a
denylistNodes given together both apply, rather than one overriding the other. The prefixes within
the label filter are ordered rather than combined — a blacklisted label wins over every other prefix,
and an end or termination label is returned without having to satisfy the whitelist.
Both relationshipFilter and labelFilter accept a single |-separated string in place of a list —
'CATCHES>|<HATES' is ['CATCHES>', '<HATES'], and '-Human|+Dog' is ['-Human', '+Dog']. Empty
pieces are ignored, so a trailing | is not an error. A | inside a list entry is not a
separator: a list entry is one whole alternative, so ['CATCHES>|<HATES'] asks for a relationship
type of that literal name and matches nothing. The same string form works on
subgraph_nodes() and subgraph_all(); the positional
expand() takes lists only.
With the default bfs: true, uniqueness: NODE_GLOBAL returns at most one path per reachable node. A node is spent by the first path that
reaches it, so a node reachable at two depths comes back only at the shorter one — and it is spent even
if a filter then rejects it, which means a minHops above every reachable node’s own depth returns no
rows at all. Several start nodes are all marked before any of them is expanded, so a start reached from
another start is returned once, as its own root rather than a second time on the path that reached it.
Which of two equal-length paths a node gets follows the order its relationships are iterated in.
RELATIONSHIP_GLOBAL, the *_LEVEL and *_RECENT modes and NONE are not supported: which paths
survive them depends on the order relationships happen to be iterated in, which is not a rule a query
can rely on. An unsupported value is reported, naming it.
maxHops is unbounded by default. A depth-first expansion — bfs: false — recurses once per hop, so it
stops with an error past a depth of 5000. The default breadth-first walk has no depth cap: it walks a
queue whose partial paths are heap, so what bounds it is memory. Set --memory-limit so an unbounded
traversal fails as a recoverable query error rather than exhausting the instance.
Output:
result: Path➡ All paths expanded from the start node(s).
Usage:
These examples use the same graph as expand().
Example 1
Return at most two paths, following outgoing CATCHES and incoming HATES, ending at a Mouse or a
Human. Because the expansion is breadth-first, the paths returned are the shortest available.
MATCH (d:Dog)
CALL path.expand_config(d, {relationshipFilter: 'CATCHES>|<HATES',
                            labelFilter: '>Mouse|>Human',
                            maxHops: 4, limit: 2}) YIELD result
RETURN [n IN nodes(result) | labels(n)[0]] AS names;
+-----------------------------------+
| names |
+-----------------------------------+
| ["Dog", "Cat", "Mouse"] |
| ["Dog", "Cat", "Mouse", "Human"] |
+-----------------------------------+Example 2
End the walk at a node named by identity rather than by label. Mouse is returned and not expanded
through, so the path stops there.
MATCH (d:Dog), (m:Mouse)
CALL path.expand_config(d, {relationshipFilter: 'CATCHES>',
                            terminatorNodes: [m], maxHops: 4}) YIELD result
RETURN [n IN nodes(result) | labels(n)[0]] AS names;
+---------------------------+
| names |
+---------------------------+
| ["Dog", "Cat", "Mouse"] |
+---------------------------+Example 3
Exclude a node by identity. With Cat on the denylist the walk cannot leave Dog, since its only
outgoing CATCHES relationship leads there.
MATCH (d:Dog), (c:Cat)
CALL path.expand_config(d, {relationshipFilter: 'CATCHES>',
                            denylistNodes: [c], maxHops: 4}) YIELD result
RETURN [n IN nodes(result) | labels(n)[0]] AS names;
+-----------+
| names |
+-----------+
| ["Dog"] |
+-----------+Example 4
Return one path per reachable node with uniqueness: NODE_GLOBAL. Every node the traversal can reach
comes back exactly once, on the shortest path that reaches it.
MATCH (h:Human)
CALL path.expand_config(h, {minHops: 0, maxHops: 4, uniqueness: 'NODE_GLOBAL'})
YIELD result
RETURN [n IN nodes(result) | labels(n)[0]] AS names;
+----------------------------+
| names |
+----------------------------+
| ["Human"] |
| ["Human", "Dog"] |
| ["Human", "Wolf"] |
| ["Human", "Mouse"] |
| ["Human", "Dog", "Cat"] |
+----------------------------+Mouse is reachable from Human directly and also through Dog and Cat; only the direct path is
returned. The same call under the default RELATIONSHIP_PATH returns 36 paths rather than these five —
every distinct route, including ones that come back to a node already on the path, since that mode only
forbids reusing a relationship.
Sequences
A filter can repeat. A comma in labelFilter or relationshipFilter separates the steps of a
sequence, and the step a node or relationship is tested against is chosen by the depth it sits at — so
the sequence starts over once the walk runs past its last step, and keeps repeating for as long as the
walk goes on.
Available on expand_config(), subgraph_nodes() and
subgraph_all(). The positional expand() takes lists of alternatives,
which cannot spell a sequence, for the same reason its signature cannot express bfs or uniqueness.
A filter written without commas is the single-step case, which repeats at every depth — so what a filter matched before sequences existed, it matches still.
Steps and alternatives
Within one step, | separates alternatives exactly as it always has, so a step can accept any of
several labels. Using the graph from expand(), each depth is tested against its own step:
MATCH (w:Wolf)
CALL path.expand_config(w, {minHops: 0, maxHops: 3, filterStartNode: true,
                            relationshipFilter: 'CATCHES>',
                            labelFilter: 'Wolf|Dog, Dog|Cat, Cat|Mouse'})
YIELD result
RETURN [n IN nodes(result) | labels(n)[0]] AS names;
+--------------------------------+
| names |
+--------------------------------+
| ["Wolf"] |
| ["Wolf", "Dog"] |
| ["Wolf", "Dog", "Cat"] |
+--------------------------------+Mouse sits at depth 3, which wraps back to the first step — Wolf|Dog — and it is neither, so the
walk ends at Cat.
A step that names no filter is an error, naming the key and the step’s 1-based position — a blank step
('Post,,Reply'), a trailing comma ('Post,'), or a step whose alternatives are all empty
('Post,|,Reply'). Each of those would otherwise read as “match everything”, which is the one thing a
filter cannot have been meant to say.
A , inside a list entry is also an error: a list entry is one alternative, so
labelFilter: ['Post,Reply'] is rejected pointing at the string form. Give the whole filter as a string
to spell a sequence.
The `sequence` key
When both kinds alternate, sequence spells them in one string — a label step, then a relationship
step, then a label step, and so on:
MATCH (w:Wolf)
CALL path.expand_config(w, {minHops: 0, maxHops: 3, filterStartNode: true,
                            sequence: 'Wolf, CATCHES>, Dog, CATCHES>, Cat, CATCHES>, Mouse'})
YIELD result
RETURN [n IN nodes(result) | labels(n)[0]] AS names;
+--------------------------------------+
| names |
+--------------------------------------+
| ["Wolf"] |
| ["Wolf", "Dog"] |
| ["Wolf", "Dog", "Cat"] |
| ["Wolf", "Dog", "Cat", "Mouse"] |
+--------------------------------------+sequence supersedes both labelFilter and relationshipFilter when it is given; they are not merged
with it. A blank or whitespace-only sequence is no sequence at all, and the two filter keys apply as
usual. Both keys are still checked for type even when a sequence supersedes them, so a mistyped one is
named rather than quietly dropped.
`beginSequenceAtStart`
By default a sequence begins at the start node: the first label step is tested against the start node, and the first relationship step against the hop out of it.
With beginSequenceAtStart: false the sequence begins one hop out. The first relationship step is
spent on the hop out of the start node and the remaining steps repeat from there, and the start node has
no label step to be tested against — so the label filter does not apply to it however filterStartNode
is set:
MATCH (w:Wolf)
CALL path.expand_config(w, {minHops: 0, maxHops: 3, beginSequenceAtStart: false,
                            relationshipFilter: 'CATCHES>,FRIENDS_WITH>'})
YIELD result
RETURN [n IN nodes(result) | labels(n)[0]] AS names;
+----------------------------------+
| names |
+----------------------------------+
| ["Wolf"] |
| ["Wolf", "Dog"] |
| ["Wolf", "Dog", "Mouse"] |
+----------------------------------+CATCHES> is spent on the single hop out of Wolf, and FRIENDS_WITH> is what repeats from Dog
onwards. With beginSequenceAtStart left at its default, CATCHES> and FRIENDS_WITH> would instead
alternate from the start node.
Because that first step is consumed, a relationship filter of only one step leaves nothing to
repeat, and beginSequenceAtStart: false alongside one is an error naming the key. The same applies to
a sequence whose relationship half has a single step.
A sequence is written relationship-first when beginSequenceAtStart is false, since its leading
step is the hop out of the start node: 'CATCHES>, Dog, FRIENDS_WITH>, Mouse', not
'Dog, CATCHES>, Mouse'. Written label-first, the leading label step is read as the initial
relationship step and nothing expands — the call returns the start node alone, with no error.
subgraph_all()
Returns a subgraph in a form of nodes and relationships that can be reached from a given start node. While traversing the graph, the function evaluates nodes based on specified criteria: it adheres to a maximum hop limit, applies relationship and label filters, and ensures each node is visited only once.
Input:
-
subgraph: Graph(OPTIONAL) ➡ A specific subgraph, which is an object of type Graph returned by theproject()function, on which the algorithm is run. If subgraph is not specified, the algorithm is computed on the entire graph by default. -
start_node: Any➡ A node, node ID, or a list of nodes and/or node IDs from which the traversing will start. -
config: Map➡ The configuration parameters. Required — pass{}to take every default:
| Name | Type | Default | Description |
|---|---|---|---|
| minHops | Int | 0 | The minimum number of hops in the traversal. Set to 0 if the start node should be included in the subgraph, or 1 otherwise. minLevel is an alias. |
| maxHops | Int | -1 | The maximum number of hops in the traversal. -1 means no limit; any other negative value matches nothing. maxLevel is an alias. |
| relationshipFilter | List or String | [ ] | Relationships which the subgraph formation will follow. Can be filtered using the notation described below. |
| labelFilter | List or String | [ ] | Labels which will define filtering. Can be filtered using the notation described below. |
| sequence | String | "" | One alternating string of label and relationship steps. Supersedes labelFilter and relationshipFilter when given. See sequences. |
| beginSequenceAtStart | Bool | True | Whether a sequence begins at the start node or one hop out from it. See sequences. |
| filterStartNode | Bool | False | Whether the label and node-identity filters apply to the start nodes. |
| limit | Int | -1 | The maximum number of nodes to return. The traversal stops once the cap is reached, so the nodes returned are the ones closest to the start. With several start nodes they are visited in the order they were listed, so that order decides which nodes a limit returns. -1 means no limit; a value below -1 is an error. |
| endNodes | List | [ ] | Nodes, or node IDs, that are returned and expanded through — the node-identity counterpart of the >LABEL prefix. With either this or terminatorNodes set, only the nodes they name are returned. |
| terminatorNodes | List | [ ] | Nodes, or node IDs, that are returned and end the walk — the node-identity counterpart of the /LABEL prefix. |
| allowlistNodes | List | [ ] | Nodes, or node IDs, the traversal is restricted to. An empty list allows every node. Nodes named by endNodes or terminatorNodes are allowed implicitly. |
| denylistNodes | List | [ ] | Nodes, or node IDs, the traversal will not return or pass through. Takes precedence over allowlistNodes. |
whitelistNodes and blacklistNodes are accepted as deprecated spellings of allowlistNodes and
denylistNodes, and are read only when the preferred key is absent or empty.
A key the procedure does not recognize is an error, naming the key, rather than being ignored — a
misspelling such as maxhops would otherwise return a different result set than was asked for. So is
supplying minHops together with minLevel, or maxHops together with maxLevel. The deprecated
node-list spellings are not rejected that way — giving both is allowed, and the preferred key wins.
bfs and uniqueness are accepted here and ignored, whatever value they are given. This traversal is
always breadth-first and visits each node once — which is what makes a node’s hop count its shortest
distance, and so what gives minHops its meaning — so neither key can ask it for anything it does not
already do.
sequence and beginSequenceAtStart do apply here, on the same terms as on
expand_config(). See sequences.
The filters combine as they do on expand_config().
Relationship filters:
| Option | Explanation |
|---|---|
TYPE | Path will expand with either outgoing or incoming relationships of this type. |
<TYPE | Path will expand with incoming relationships of this type. |
TYPE> | Path will expand with outgoing relationships of this type. |
> | Path will expand with all outgoing relationships. |
< | Path will expand will all incoming relationships. |
If the relationship filter is empty, all relationship types are allowed.
The notation is described in full under expand(): where a direction marker may appear
and which one wins, how two entries for the same type merge, and which entries are errors. This
procedure also accepts the |-separated string form — see expand_config().
Examples:
Relationship list : [<LOVES, >]: The path will expand on all outgoing relationships, and incoming relationshipLOVES.Relationship list : [<LOVES, LOVES]: The path will expand on incoming relationshipLOVES, and all directions of relationshipLOVES, making the first element in the relationship list functionally obsolete.Relationship list : []: The path will expand on all relationships.
Label filters:
Label filters are described in the table below:
| Option | Explanation |
|---|---|
+LABEL | Label is added to the whitelist. All nodes in the path must have a label in the whitelist. If the whitelist is empty, it is as if all nodes are whitelisted. |
>LABEL | Label is added to the end list. When end list has labels, only paths ending with these labels will be returned, but they can be expanded further, to return paths ending in nodes with end labels beyond it. An end-listed node is expanded through whether or not it is whitelisted; every other node on the path must satisfy the whitelist. |
-LABEL | Label is added to the blacklist. No node in the path will contain labels in the blacklist. The blacklist takes precedence over all other filters. |
/LABEL | Label is added to the termination list. When termination list contains labels, only paths ending with these labels will be returned, and any further expansion is stopped. Labels in the termination list do not have to respect the whitelist. |
* | Matches every label, under any of the four prefixes. * and +* whitelist every node, -* blacklists every one, >* makes every node an end node and /* a termination node. This is how one step of a sequence says “any label in this position”. |
The notation is described in full under expand(): the * wildcard under each prefix,
why * is not a relationship wildcard, which entries are errors, how filterStartNode affects the
start node, and when a termination label ends the walk.
Any other label syntax is added to the whitelist. For example, LABEL will be
added to the whitelist as LABEL, and !LABEL will be added to the whitelist
as !LABEL.
To know where the label will be added, look at the first element of the label.
For example, >LABEL> will be added to the end list as LABEL>.
Examples
Consider the graph provided in the usage section below. In this subsection, number of hops will be limited from 0 to 2, and the starting node will be Dog.
Label list: ["/Mouse"]- The filtering will return all the paths ending withMouse. Because no labels were added to the whitelist, all labels are considered whitelisted. This filtering will return 3 paths:Dog->Cat->Mouse,Dog<-Human->Mouse,Dog->Mouse.Label list: ["/Mouse", "Cat"]- Now, labelCatis added to the whitelist, becoming the only whitelisted label. The meaning of the filter can now be represented as:"return all paths ending with Mouse, which expand through Cat and Cat only". This filtering will return two paths, one whereDogconnects to theMousedirectly (Dog->Mouse), and one whereCatis included (Dog->Cat->Mouse).Label list: ["/Mouse", "-Cat", "-Human"]- Now, bothCatandHumanare blacklisted, and there is only one eligible path that can reachMouse:Dog->Mouse.
For the final example, the starting node is Cat, and the maximum number of
hops is increased to 4.
Label list: [">Dog", "+Human", "+Wolf"]- Now, only paths ending withDogwill be returned, but they can be further expanded through the nodes with whitelisted labels. This filtering returns 3 paths:Cat<-Dog,Cat<-Dog<-Human->Wolf->Dog,Cat<-Dog<-Wolf<-Human->Dog.
Output:
nodes: List[Node]➡ A list of nodes which form the subgraph.rels: List[Relationship]➡ A list of relationships which form the subgraph. This is every relationship between the returned nodes, so a relationship whose typerelationshipFilterexcluded is still returned when both its endpoints are innodes.
Usage:
The database contains the following data:
Created with the following Cypher queries:
CREATE (w:Wolf)-[ca:CATCHES]->(d:Dog), (c:Cat), (m:Mouse), (h:Human);
MATCH (w:Wolf), (d:Dog), (c:Cat), (m:Mouse), (h:Human)
WITH w, d, c, m, h
CREATE (d)-[:CATCHES]->(c)
CREATE (c)-[:CATCHES]->(m)
CREATE (d)-[:FRIENDS_WITH]->(m)
CREATE (h)-[:OWNS]->(d)
CREATE (h)-[:HUNTS]->(w)
CREATE (h)-[:HATES]->(m);
Example 1
Create a subgraph from Dog on outgoing relationship CATCHES and incoming
relationship HATES, with Mouse and Human being labels in end list.
Whitelist is empty, hence, all labels are whitelisted.
MATCH (w:Wolf), (d:Dog), (c:Cat), (m:Mouse), (h:Human)
CALL path.subgraph_all(d, {
      relationshipFilter: ["CATCHES>","<HATES"],
      labelFilter: [">Mouse", ">Human"],
      minHops: 0,
      maxHops: 4
})
YIELD nodes, rels
RETURN nodes, rels;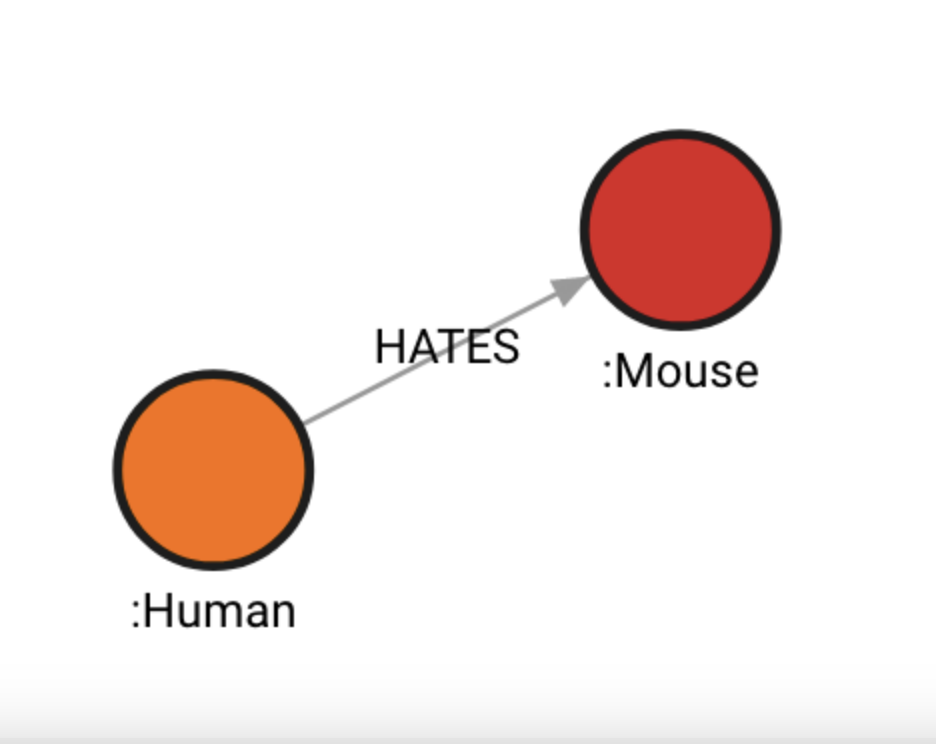
The results should be identical to the ones below, except for the id values
that depend on the internal database id values.
 +----------------------------+----------------------------+
 | nodes                      | rels                       |
 +----------------------------+----------------------------+
 | {                          | {                          |
 |     "id": 3,               |     "id": 6,               |
 |     "labels": [            |     "start": 4,            |
 |        "Mouse"             |     "end": 3,              |
 |     ],                     |     "label": "HATES",      |
 |     "properties": {},      |     "properties": {},      |
 |     "type": "node"         |     "type": "relationship" |
 | }                          | }                          |
 +----------------------------+----------------------------+
 | {                          |                            |
 |     "id": 4,               |                            |
 |     "labels": [            |                            |
 |        "Human"             |                            |
 |     ],                     |                            |
 |     "properties": {},      |                            |
 |     "type": "node"         |                            |
 | }                          |                            |
 +----------------------------+----------------------------+
Example 2
Create subgraph from Dog only on incoming relationships. Also, Human is blacklisted.
MATCH (w:Wolf), (d:Dog), (c:Cat), (m:Mouse), (h:Human)
CALL path.subgraph_all(d, {
      relationshipFilter: ["<"],
      labelFilter: ["-Human"],
      minHops: 0,
      maxHops: 4
})
YIELD nodes, rels
RETURN nodes, rels;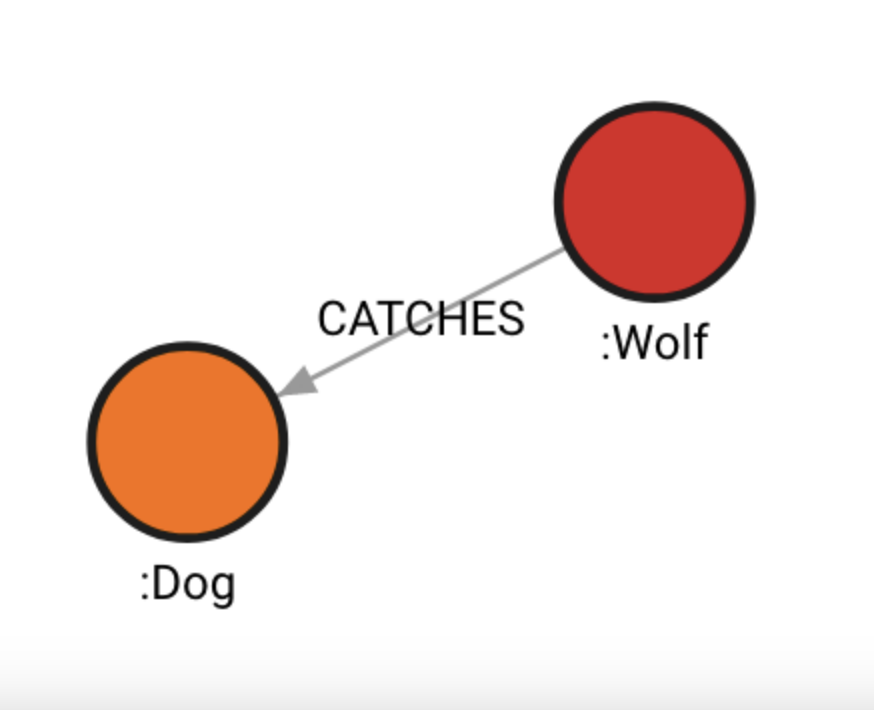
The results should be identical to the ones below, except for the id values that depend on the internal database id values.
 +----------------------------+----------------------------+
 | nodes                      | rels                       |
 +----------------------------+----------------------------+
 | {                          | {                          |
 |     "id": 1,               |     "id": 0,               |
 |     "labels": [            |     "start": 0,            |
 |        "Dog"               |     "end": 1,              |
 |     ],                     |     "label": "CATCHES",    |
 |     "properties": {},      |     "properties": {},      |
 |     "type": "node"         |     "type": "relationship" |
 | }                          | }                          |
 +----------------------------+----------------------------+
 | {                          |                            |
 |     "id": 0,               |                            |
 |     "labels": [            |                            |
 |        "Wolf"              |                            |
 |     ],                     |                            |
 |     "properties": {},      |                            |
 |     "type": "node"         |                            |
 | }                          |                            |
 +----------------------------+----------------------------+
subgraph_nodes()
The procedure returns a subgraph made out of those nodes that can be reached from a given start node. While traversing the graph, the function evaluates nodes based on specified criteria: it adheres to a maximum hop limit, applies relationship and label filters, and ensures each node is visited only once.
Input:
subgraph: Graph(OPTIONAL) ➡ A specific subgraph, which is an object of type Graph returned by theproject()function, on which the algorithm is run. If subgraph is not specified, the algorithm is computed on the entire graph by default.start_node: Any➡ A node, node ID, or a list of nodes and/or node IDs from which the traversing will start.config: Map➡ Configuration parameters. Required — pass{}to take every default:
| Name | Type | Default | Description |
|---|---|---|---|
| minHops | Int | 0 | The minimum number of hops in the traversal. Set to 0 if the start node should be included in the subgraph, or 1 otherwise. minLevel is an alias. |
| maxHops | Int | -1 | The maximum number of hops in the traversal. -1 means no limit; any other negative value matches nothing. maxLevel is an alias. |
| relationshipFilter | List or String | [ ] | Relationships which the subgraph formation will follow. Explained in detail below. |
| labelFilter | List or String | [ ] | Labels which will define filtering. Explained in detail below. |
| sequence | String | "" | One alternating string of label and relationship steps. Supersedes labelFilter and relationshipFilter when given. See sequences. |
| beginSequenceAtStart | Bool | True | Whether a sequence begins at the start node or one hop out from it. See sequences. |
| filterStartNode | Bool | False | Whether the label and node-identity filters apply to the start nodes. |
| limit | Int | -1 | The maximum number of nodes to return. The traversal stops once the cap is reached, so the nodes returned are the ones closest to the start. With several start nodes they are visited in the order they were listed, so that order decides which nodes a limit returns. -1 means no limit; a value below -1 is an error. |
| endNodes | List | [ ] | Nodes, or node IDs, that are returned and expanded through — the node-identity counterpart of the >LABEL prefix. With either this or terminatorNodes set, only the nodes they name are returned. |
| terminatorNodes | List | [ ] | Nodes, or node IDs, that are returned and end the walk — the node-identity counterpart of the /LABEL prefix. |
| allowlistNodes | List | [ ] | Nodes, or node IDs, the traversal is restricted to. An empty list allows every node. Nodes named by endNodes or terminatorNodes are allowed implicitly. |
| denylistNodes | List | [ ] | Nodes, or node IDs, the traversal will not return or pass through. Takes precedence over allowlistNodes. |
whitelistNodes and blacklistNodes are accepted as deprecated spellings of allowlistNodes and
denylistNodes, and are read only when the preferred key is absent or empty.
A key the procedure does not recognize is an error, naming the key, rather than being ignored — a
misspelling such as maxhops would otherwise return a different result set than was asked for. So is
supplying minHops together with minLevel, or maxHops together with maxLevel. The deprecated
node-list spellings are not rejected that way — giving both is allowed, and the preferred key wins.
bfs and uniqueness are accepted here and ignored, whatever value they are given. This traversal is
always breadth-first and visits each node once — which is what makes a node’s hop count its shortest
distance, and so what gives minHops its meaning — so neither key can ask it for anything it does not
already do.
sequence and beginSequenceAtStart do apply here, on the same terms as on
expand_config(). See sequences.
The filters combine as they do on expand_config().
Relationship filters
| Option | Explanation |
|---|---|
TYPE | Path will expand with either outgoing or incoming relationships of this type. |
<TYPE | Path will expand with incoming relationships of this type. |
TYPE> | Path will expand with outgoing relationships of this type. |
> | Path will expand with all outgoing relationships. |
< | Path will expand will all incoming relationships. |
If the relationship filter is empty, all relationship types are allowed.
The notation is described in full under expand(): where a direction marker may appear
and which one wins, how two entries for the same type merge, and which entries are errors. This
procedure also accepts the |-separated string form — see expand_config().
Examples:
Relationship list : [<LOVES, >]: The path will expand on all outgoing relationships, and incoming relationshipLOVES.Relationship list : [<LOVES, LOVES]: The path will expand on incoming relationshipLOVES, and all directions of relationshipLOVES, making the first element in the relationship list functionally obsolete.Relationship list : []: The path will expand on all relationships.
Label filter
| Option | Explanation |
|---|---|
+LABEL | Label is added to the whitelist. All nodes in the path must have a label in the whitelist. If the whitelist is empty, it is as if all nodes are whitelisted. |
>LABEL | Label is added to the end list. When end list has labels, only paths ending with these labels will be returned, but they can be expanded further, to return paths ending in nodes with end labels beyond it. An end-listed node is expanded through whether or not it is whitelisted; every other node on the path must satisfy the whitelist. |
-LABEL | Label is added to the blacklist. No node in the path will contain labels in the blacklist. The blacklist takes precedence over all other filters. |
/LABEL | Label is added to the termination list. When termination list contains labels, only paths ending with these labels will be returned, and any further expansion is stopped. Labels in the termination list do not have to respect the whitelist. |
* | Matches every label, under any of the four prefixes. * and +* whitelist every node, -* blacklists every one, >* makes every node an end node and /* a termination node. This is how one step of a sequence says “any label in this position”. |
The notation is described in full under expand(): the * wildcard under each prefix,
why * is not a relationship wildcard, which entries are errors, how filterStartNode affects the
start node, and when a termination label ends the walk.
Any other label syntax is added to the whitelist. For example, LABEL will be added to the whitelist as LABEL, and !LABEL will be added to the whitelist as !LABEL. NOTE: when deciding where the label will be added, it is done by looking at the first element of the label. For example, >LABEL> will be added to the end list as LABEL>.
Examples:
Consider the graph provided in the usage section below. In this subsection, number of hops will be limited from 0 to 2, and the starting node will be Dog.
Label list: ["/Mouse"]- The filtering will return all the paths ending withMouse. Because no labels were added to the whitelist, all labels are considered whitelisted. This filtering will return 3 paths:Dog->Cat->Mouse,Dog<-Human->Mouse,Dog->Mouse.Label list: ["/Mouse", "Cat"]- Now, labelCatis added to the whitelist, becoming the only whitelisted label. The meaning of the filter can now be represented as:"return all paths ending with Mouse, which expand through Cat and Cat only". This filtering will return two paths, one whereDogconnects to theMousedirectly (Dog->Mouse), and one whereCatis included (Dog->Cat->Mouse).Label list: ["/Mouse", "-Cat", "-Human"]- Now, bothCatandHumanare blacklisted, and there is only one eligible path that can reachMouse:Dog->Mouse.
For the final example, the starting node is Cat, and the maximum number of
hops is increased to 4.
Label list: [">Dog", "+Human", "+Wolf"]- Now, only paths ending withDogwill be returned, but they can be further expanded through the nodes with whitelisted labels. This filtering returns 3 paths:Cat<-Dog,Cat<-Dog<-Human->Wolf->Dog,Cat<-Dog<-Wolf<-Human->Dog.
Output:
nodes: Node➡ The nodes that form the subgraph.
Usage:
The database contains the following data:
Created with the following Cypher queries:
CREATE (w:Wolf)-[ca:CATCHES]->(d:Dog), (c:Cat), (m:Mouse), (h:Human);
MATCH (w:Wolf), (d:Dog), (c:Cat), (m:Mouse), (h:Human)
WITH w, d, c, m, h
CREATE (d)-[:CATCHES]->(c)
CREATE (c)-[:CATCHES]->(m)
CREATE (d)-[:FRIENDS_WITH]->(m)
CREATE (h)-[:OWNS]->(d)
CREATE (h)-[:HUNTS]->(w)
CREATE (h)-[:HATES]->(m);
Example 1
Create a subgraph from Dog on outgoing relationship CATCHES and incoming
relationship HATES, with Mouse and Human being labels in end list.
Whitelist is empty, hence, all labels are whitelisted.
MATCH (w:Wolf), (d:Dog), (c:Cat), (m:Mouse), (h:Human)
CALL path.subgraph_nodes(d, {
      relationshipFilter: ["CATCHES>","<HATES"],
      labelFilter: [">Mouse", ">Human"],
      minHops: 0,
      maxHops: 4
})
YIELD nodes
RETURN nodes;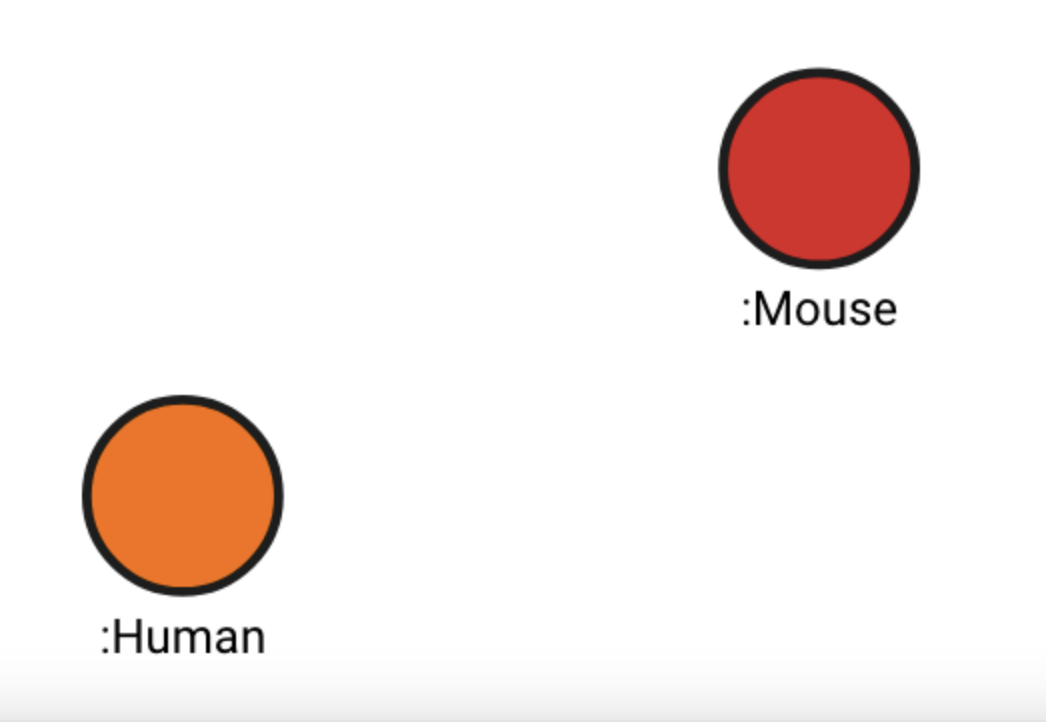
The results should be identical to the ones below, except for the id values
that depend on the internal database id values.
 +----------------------------+
 | nodes                      |
 +----------------------------+
 | {                          |
 |     "id": 3,               |
 |     "labels": [            |
 |        "Mouse"             |
 |     ],                     |
 |     "properties": {},      |
 |     "type": "node"         |
 | }                          |
 +----------------------------+
 | {                          |
 |     "id": 4,               |
 |     "labels": [            |
 |        "Human"             |
 |     ],                     |
 |     "properties": {},      |
 |     "type": "node"         |
 | }                          |
 +----------------------------+
Example 2
Create subgraph from Dog only on incoming relationships. Also, Human is
blacklisted.
MATCH (w:Wolf), (d:Dog), (c:Cat), (m:Mouse), (h:Human)
CALL path.subgraph_nodes(d, {
      relationshipFilter: ["<"],
      labelFilter: ["-Human"],
      minHops: 0,
      maxHops: 4
})
YIELD nodes
RETURN nodes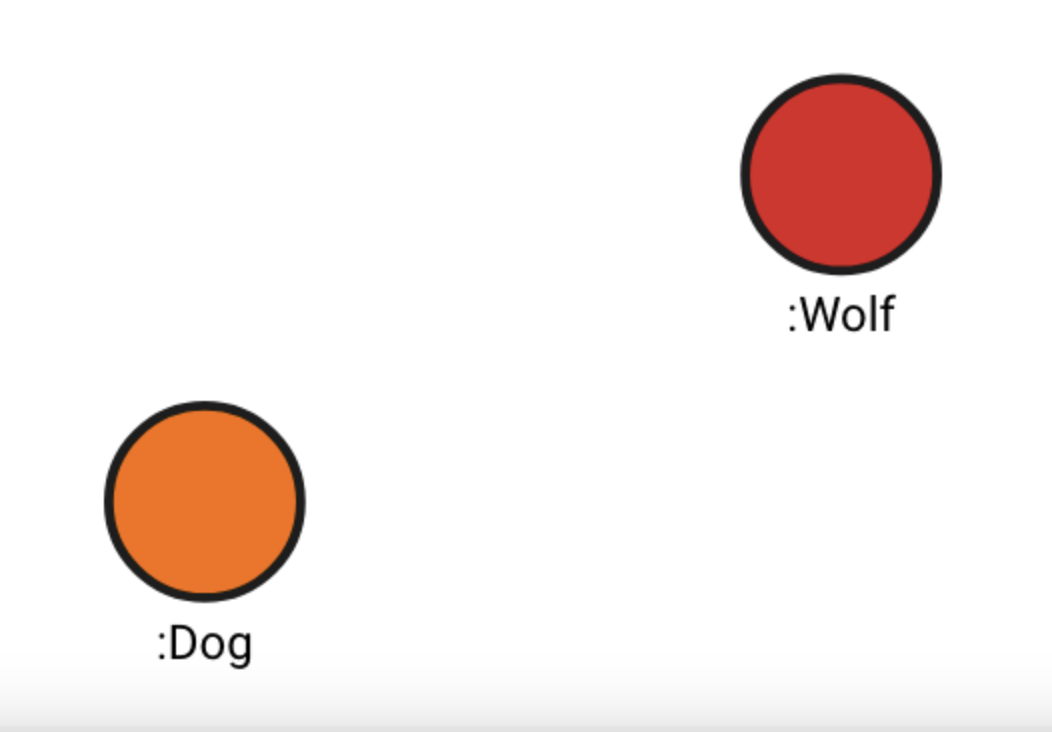
The results should be identical to the ones below, except for the id values
that depend on the internal database id values.
 +----------------------------+
 | nodes                      |
 +----------------------------+
 | {                          |
 |     "id": 1,               |
 |     "labels": [            |
 |        "Dog"               |
 |     ],                     |
 |     "properties": {},      |
 |     "type": "node"         |
 | }                          |
 +----------------------------+
 | {                          |
 |     "id": 0,               |
 |     "labels": [            |
 |        "Wolf"              |
 |     ],                     |
 |     "properties": {},      |
 |     "type": "node"         |
 | }                          |
 +----------------------------+