


4 Real-World Success Stories Where GraphRAG Beats Standard RAG
Teams building LLM applications on Memgraph usually run into the same question early, "Is vector retrieval enough, or does the workload depend on reasoning across relationships?"
Standard RAG works well when the job is to retrieve the most relevant passage from unstructured text. It becomes less reliable when answers depend on connected entities, rapidly changing operational data, or multi-step reasoning across people, systems, documents, and events.
This is where GraphRAG helps. GraphRAG doesn't replace vector search. In most of the examples below, vector search still finds where to start, and the graph supplies the relationships from there.
Instead of relying only on isolated text chunks, GraphRAG connects the model to a live knowledge graph that can be queried as needed.
With GraphRAG, LLMs can:
- Work from current data, because they query the graph when the question is asked.
- Ground answers in retrieved facts and point to their sources.
- Answer multi-hop questions that connect facts across documents and systems.
- Keep sensitive data in-house when paired with a privately hosted LLM and read-only access.
Here are four real-world examples of teams building GraphRAG on Memgraph to make LLM outputs more accurate and useful.
1. NASA: A People Knowledge Graph for Workforce Intelligence
NASA had a people problem. Not a personnel issue, but a data one. With about 18,000 employees, overlapping projects, and knowledge spread across a data warehouse, resumes, and project descriptions, finding out who knew what was slow and hard to scale.
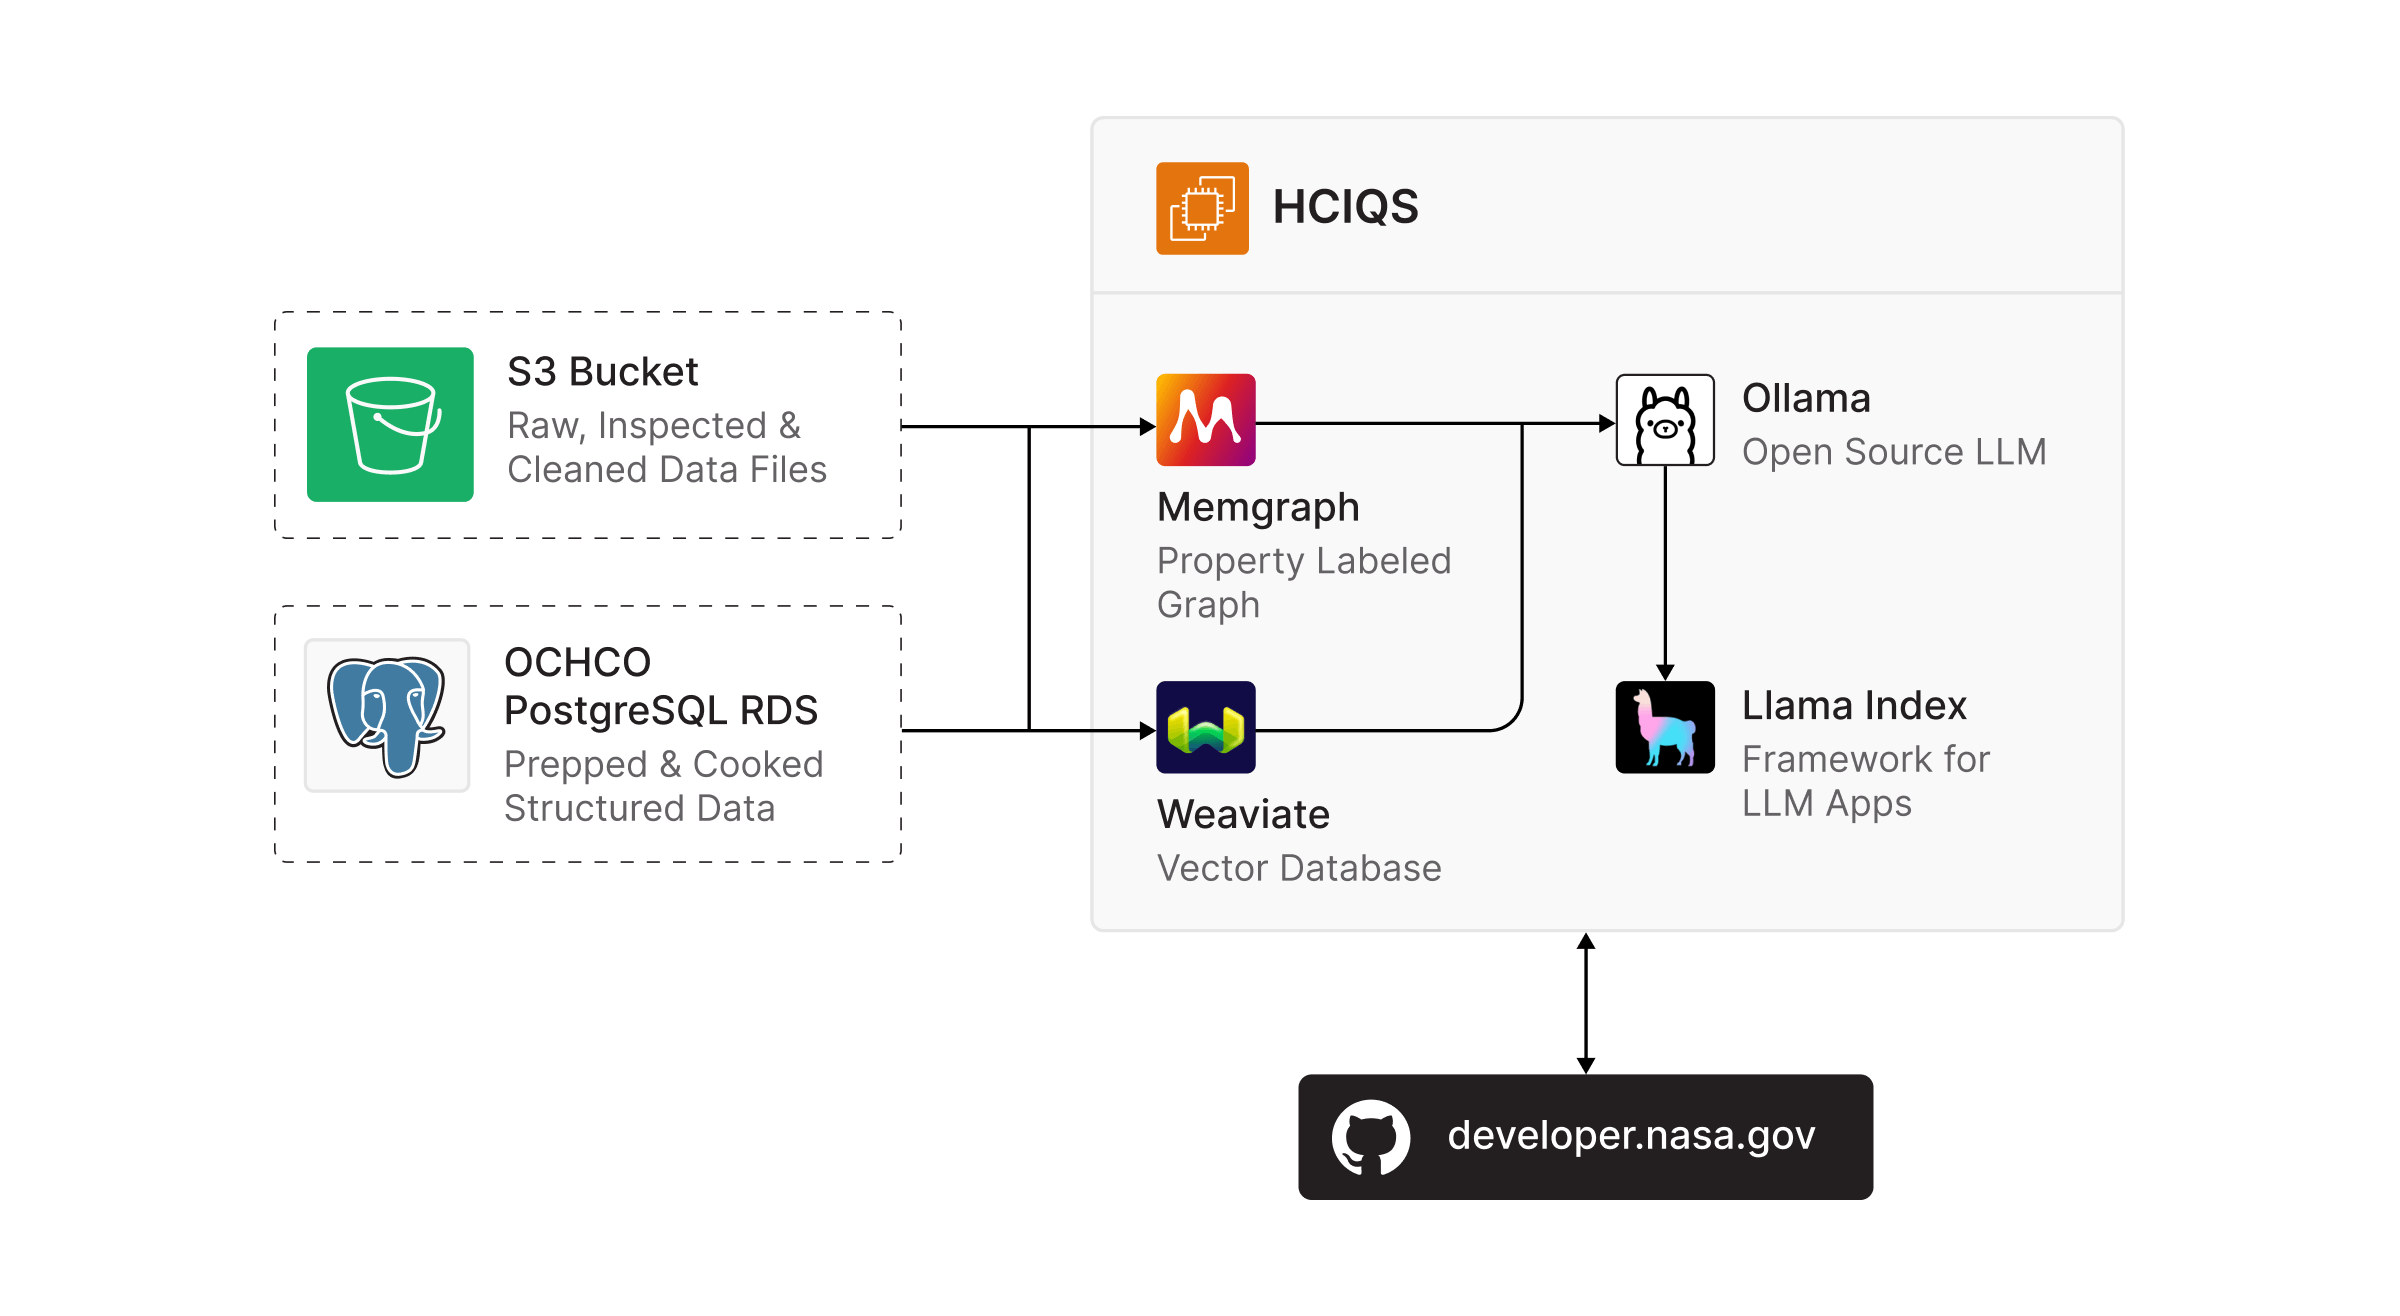
To address this, NASA's People Analytics team built a People Knowledge Graph in Memgraph, connecting employees to their projects, organizations, education, and skills. In pilot testing, it held over 27,000 nodes and 230,000 relationships.
On top of this graph, the team began building retrieval-augmented generation (RAG) pipelines, using LLMs to extract and enrich people data from unstructured sources such as resumes and project descriptions.
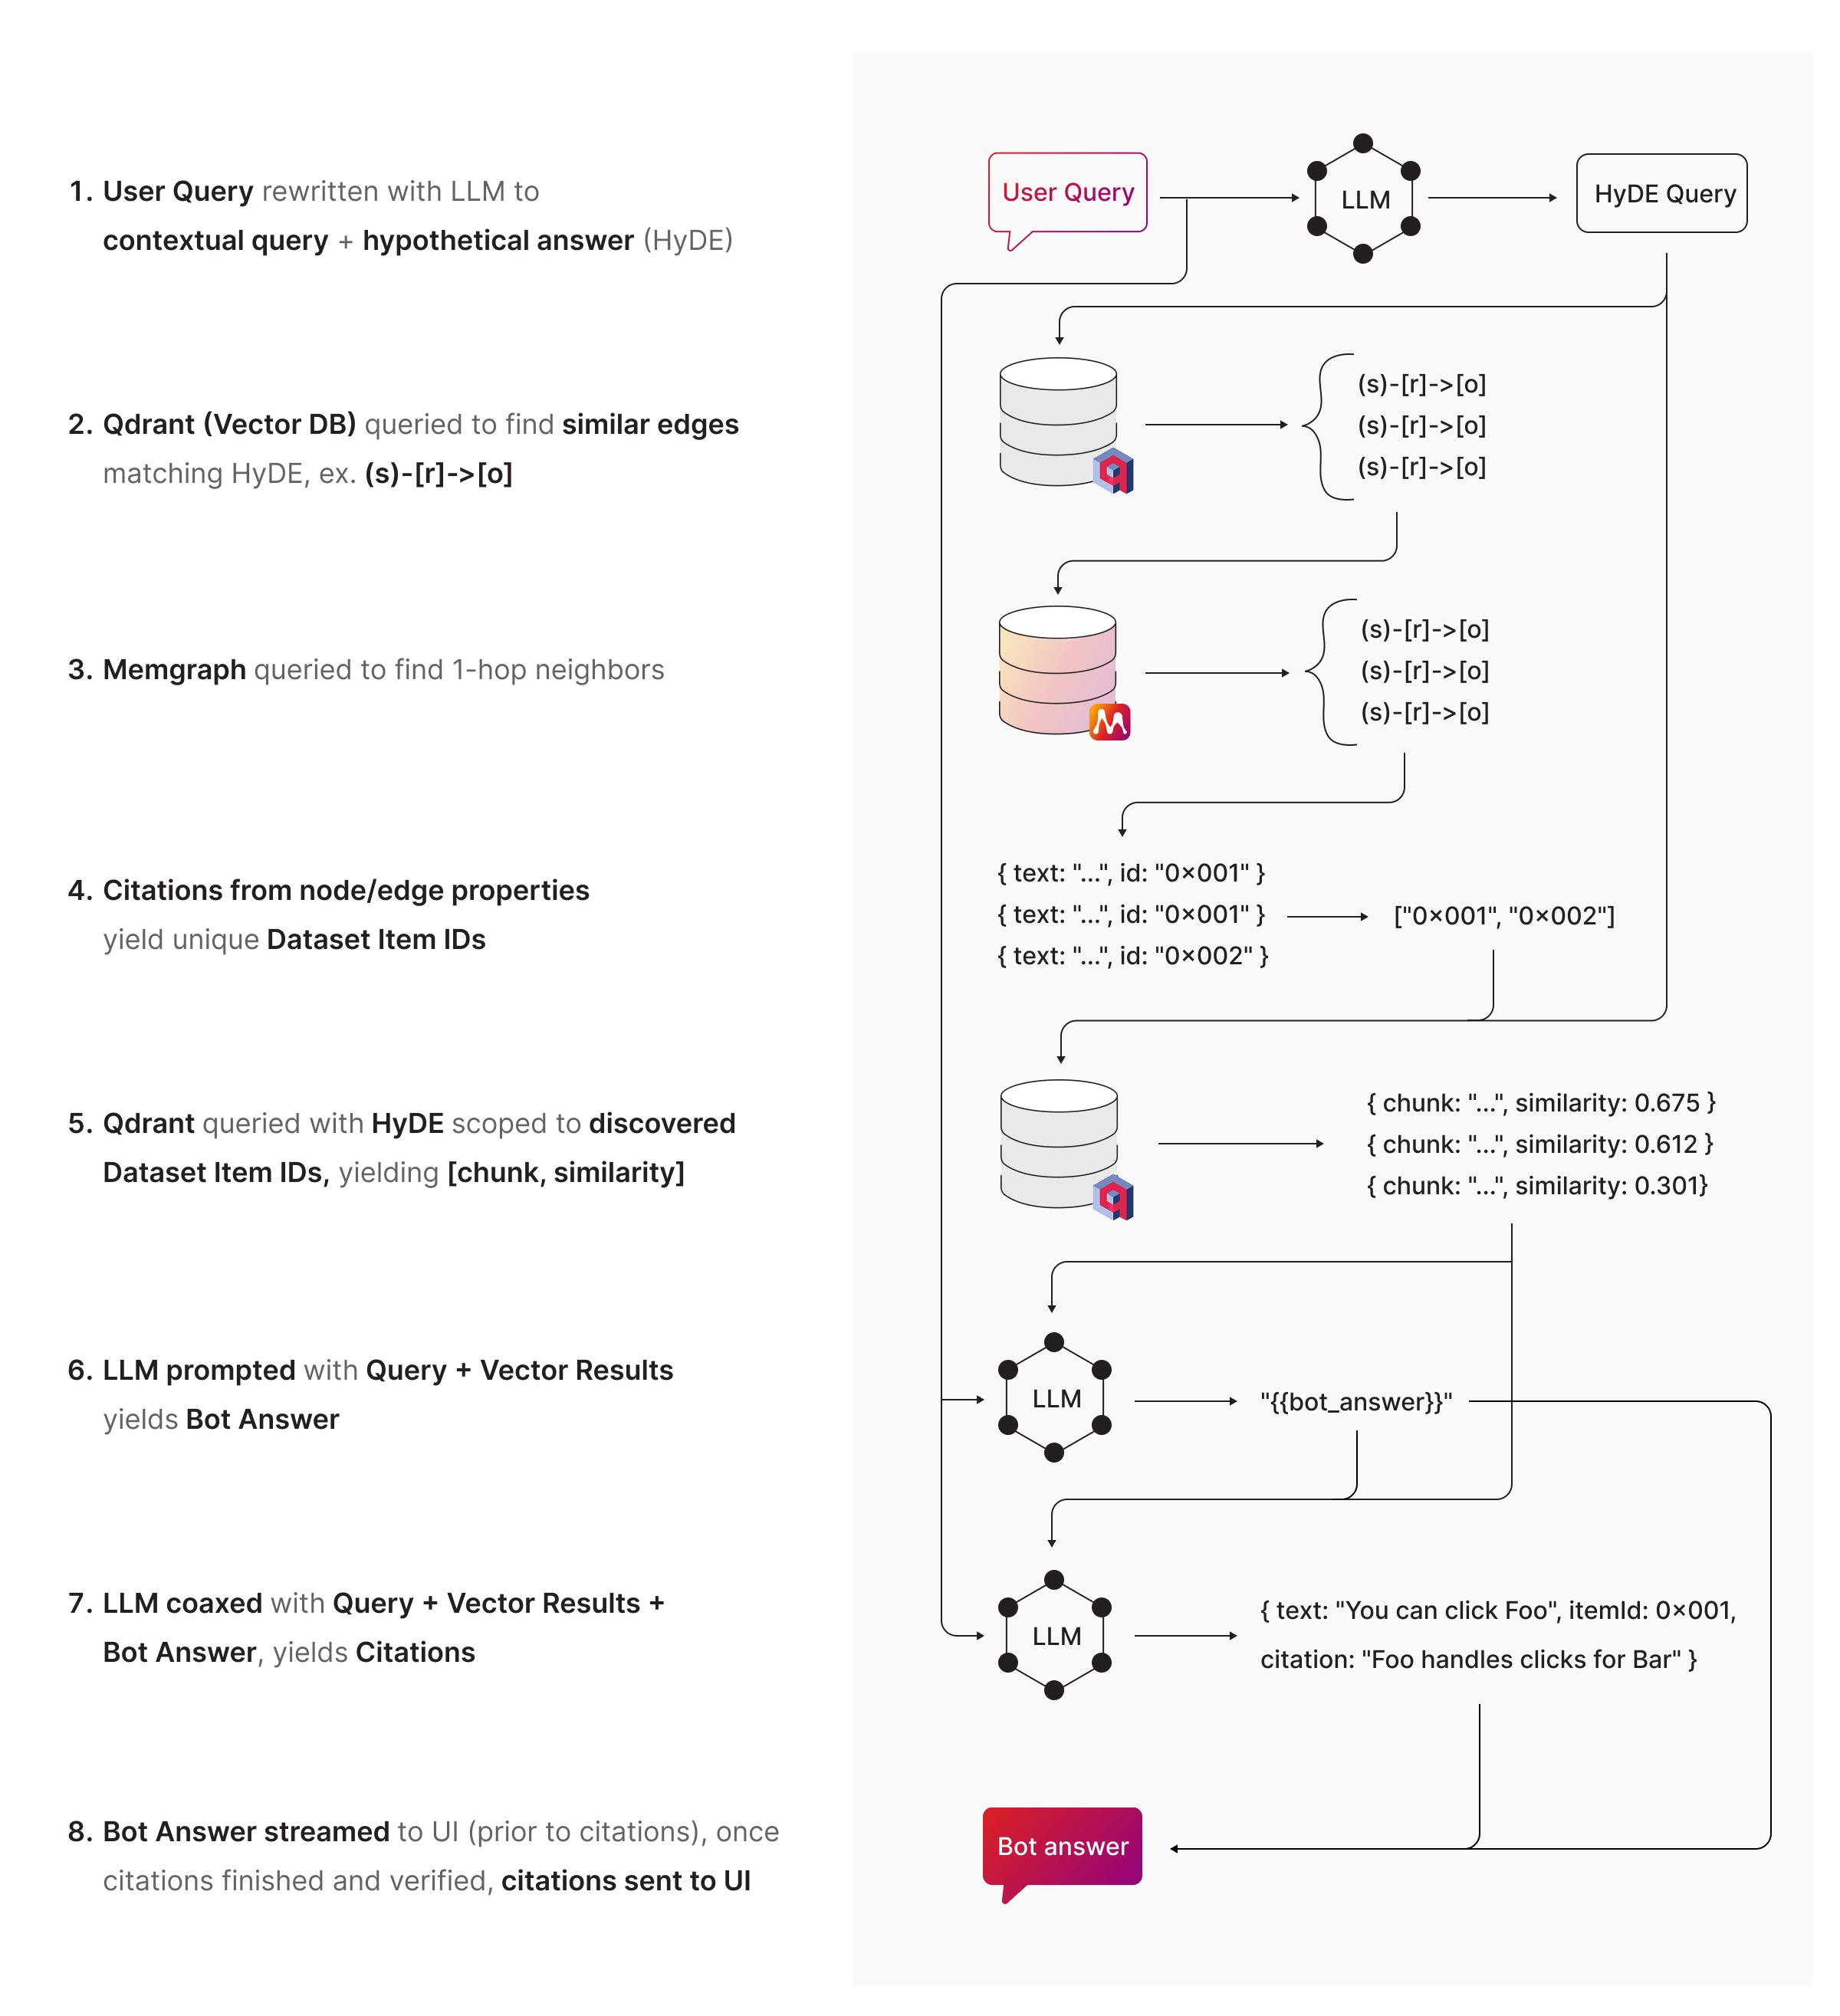
The GraphRAG pipeline was designed to pull the intent, context, and sentiment out of a natural-language question, so employees could ask complex workforce questions without writing Cypher.
A vector-only RAG system would likely fall short here. For example, if someone searched “Who worked on autonomous space robotics?” a vector model might match resumes or documents that mention those words, even in unrelated contexts. It might return someone who once referenced “robotics” in a seminar and “space” in a training course.
GraphRAG works from the relationships instead. In the case of NASA, their system finds the people and projects a question mentions, follows their relationships two hops out, and passes those connections to an LLM running on NASA's own servers. That grounds the answer in the project history recorded in the graph.
The results? The People Knowledge Graph lets the team pilot skill-gap detection, subject-matter-expert discovery, and project-overlap discovery. It also lays the foundation for LLM-powered GraphRAG pipelines that make workforce questions easier to ask.
Read Full Story | Watch Full Community Call
2. Precina Health: Optimizing Diabetes Management
Managing chronic conditions like Type 2 diabetes is a global health challenge.
Precina Health treats it by looking at each patient's whole situation, connecting clinical care with the social and behavioral factors that affect blood sugar.
Precina's care model combines clinical care with social determinants of health and behavioral insights, and GraphRAG is part of the technology behind it.
They built a GraphRAG system, named P3C (Provider-Patient CoPilot), that connected medical records with social and behavioral data in real time. Alongside A1C levels, providers get context on why those levels might rise or fall, such as a missed bus or a stressful week. P3C surfaces those insights in a side panel while the provider is talking with the patient. Here’s how it works:
Josiah Bryan, Precina's CTO, says vector RAG alone is sometimes good enough. The graph earns its place when an answer needs facts from many different parts of the data. He describes vector search as a kind of "teleportation device" that jumps to the right part of the graph, where the relationships take over.
The results? Precina reports a 1% monthly drop in patients' HbA1C, about 12 times the roughly 1% a year that a successful diabetes medication achieves.
Read Full Story | Watch Full Community Call
3. Cedars-Sinai: Knowledge-Aware Automated Machine Learning in Alzheimer’s Research
Alzheimer's research depends on connections across genes, drugs, and clinical evidence. Cedars-Sinai's Alzheimer's Disease Knowledge Base (AlzKB) captures them in Memgraph, with over 234,000 nodes and 1.67 million relationships drawn from more than 20 biomedical sources.
To let biologists and clinicians query AlzKB without learning Cypher, Cedars-Sinai first tried GPT-4 on its own, which did little better than a coin flip on questions about the graph. The team then built KRAGEN (Knowledge Retrieval Augmented Generation ENgine), which turns paths in the graph into vectors, retrieves them with RAG, and breaks complex questions into smaller steps.
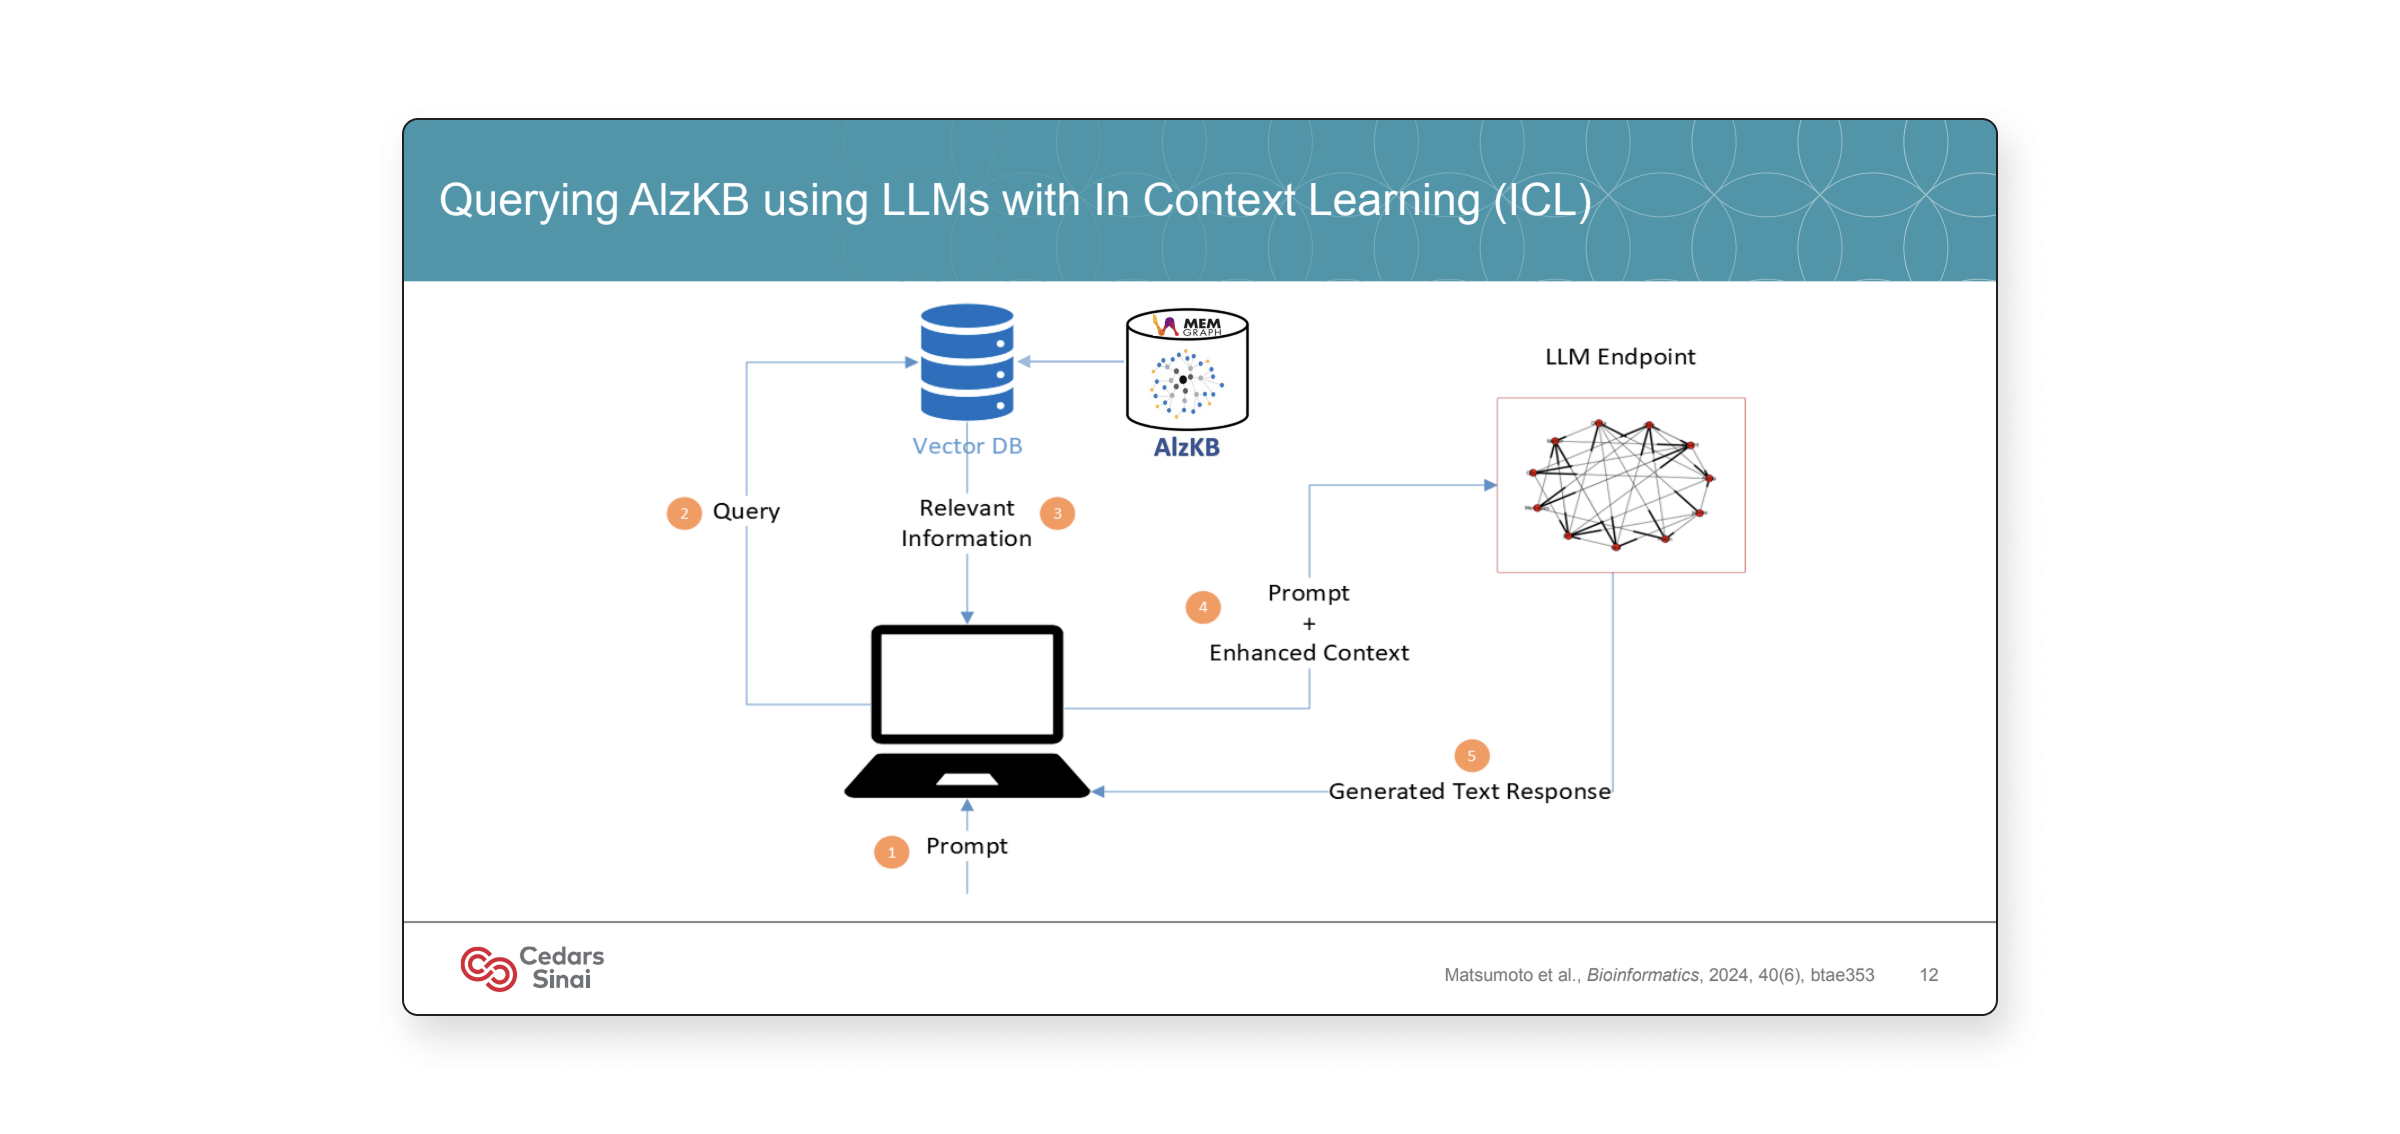
Their next agent, ESCARGOT, skips the vector step. It breaks a question into parts and writes Cypher to query Memgraph directly. In Cedars-Sinai's testing, ESCARGOT reached 94.2% accuracy on multi-hop questions, against 49.9% for ChatGPT on its own. In the peer-reviewed ESCARGOT paper, it answered 85.8% of 450 open-ended two-hop questions correctly, against 23.1% for a standard vector RAG setup.
The gap was widest on open-ended questions that need one or two hops through the graph, where standard RAG struggled and ESCARGOT's direct Cypher queries held up.
The results? Beyond question answering, AlzKB also guides Cedars-Sinai's automated machine learning toward gene and drug connections it would otherwise miss. That work identified Temazepam and Ibuprofen as potential Alzheimer's therapies worth investigating.
Read Full Story | Watch Full Community Call
4. Microchip: A GraphRAG Assistant for Customer Support
Microchip Technology's customer service team couldn't directly access the data needed to answer order status or production-related inquiries. Instead, they had to rely on engineering or operations teams—creating delays, bottlenecks, and internal inefficiencies.
To solve this, they built a "Workspace Assistant," a GraphRAG-powered chatbot supported by Memgraph and a private custom LLM. Unlike traditional RAG systems, this assistant was able to answer domain-specific queries by retrieving structured insights from real-time operational graphs.
For example, when a customer asked why their sales order was late, a customer service agent could ask the assistant. Its private LLM used the graph schema to write a Cypher query (Text2Cypher), ran it in Memgraph, and summarized the result, citing the order's reason codes and the stages where it ran late. A follow-up question pulled up the work plans in place to improve the ship date.
The solution offered more than just faster answers. It enabled:
- Secure and role-based access to internal data using Memgraph’s enterprise-grade access control.
- Scalable architecture to support multiple business units, each with different data retrieval needs.
- An agent-based architecture with a universal interface that separated user interaction, chain selection, and response generation for better modularity and flexibility.
The results? Microchip's customer service team gained instant, intuitive access to complex data. Meanwhile, engineering and ops teams were freed from routine query handling, letting them focus on high-priority work.
Read Full Story | Watch Full Community Call
When to Choose GraphRAG
These examples point to a practical decision:
- Use standard RAG when your main goal is retrieving the right document or passage from unstructured text.
- Use GraphRAG when the answer depends on relationships, multi-hop reasoning, or live operational context across connected entities.
In Memgraph today, each of these patterns maps to a GraphRAG retrieval pipeline that runs as a single Cypher query.
| Team | Example question | How they retrieve | Pipeline today |
|---|---|---|---|
| NASA | "What projects does this person work on?" | Pivot search, then two-hop expansion | Local graph search |
| Precina Health | Questions about a patient's history and records | Vector search on relationships, then one-hop neighbors in Memgraph | Local graph search |
| Cedars-Sinai | "Which body parts overexpress both of these genes?" | The LLM writes Cypher for each sub-question | Text2Cypher |
| Microchip | "Why is this sales order late?" | Text2Cypher, with an agent choosing the tool for each department | Text2Cypher, agent-selected as in Agentic GraphRAG |
If your LLM workflow falls into the second category, start with GraphRAG with Memgraph, which includes a one-command demo of all three pipelines. Then follow the guidelines about how GraphRAG works in the Memgraph docs to quickly get started.
